Lifecycle hooks
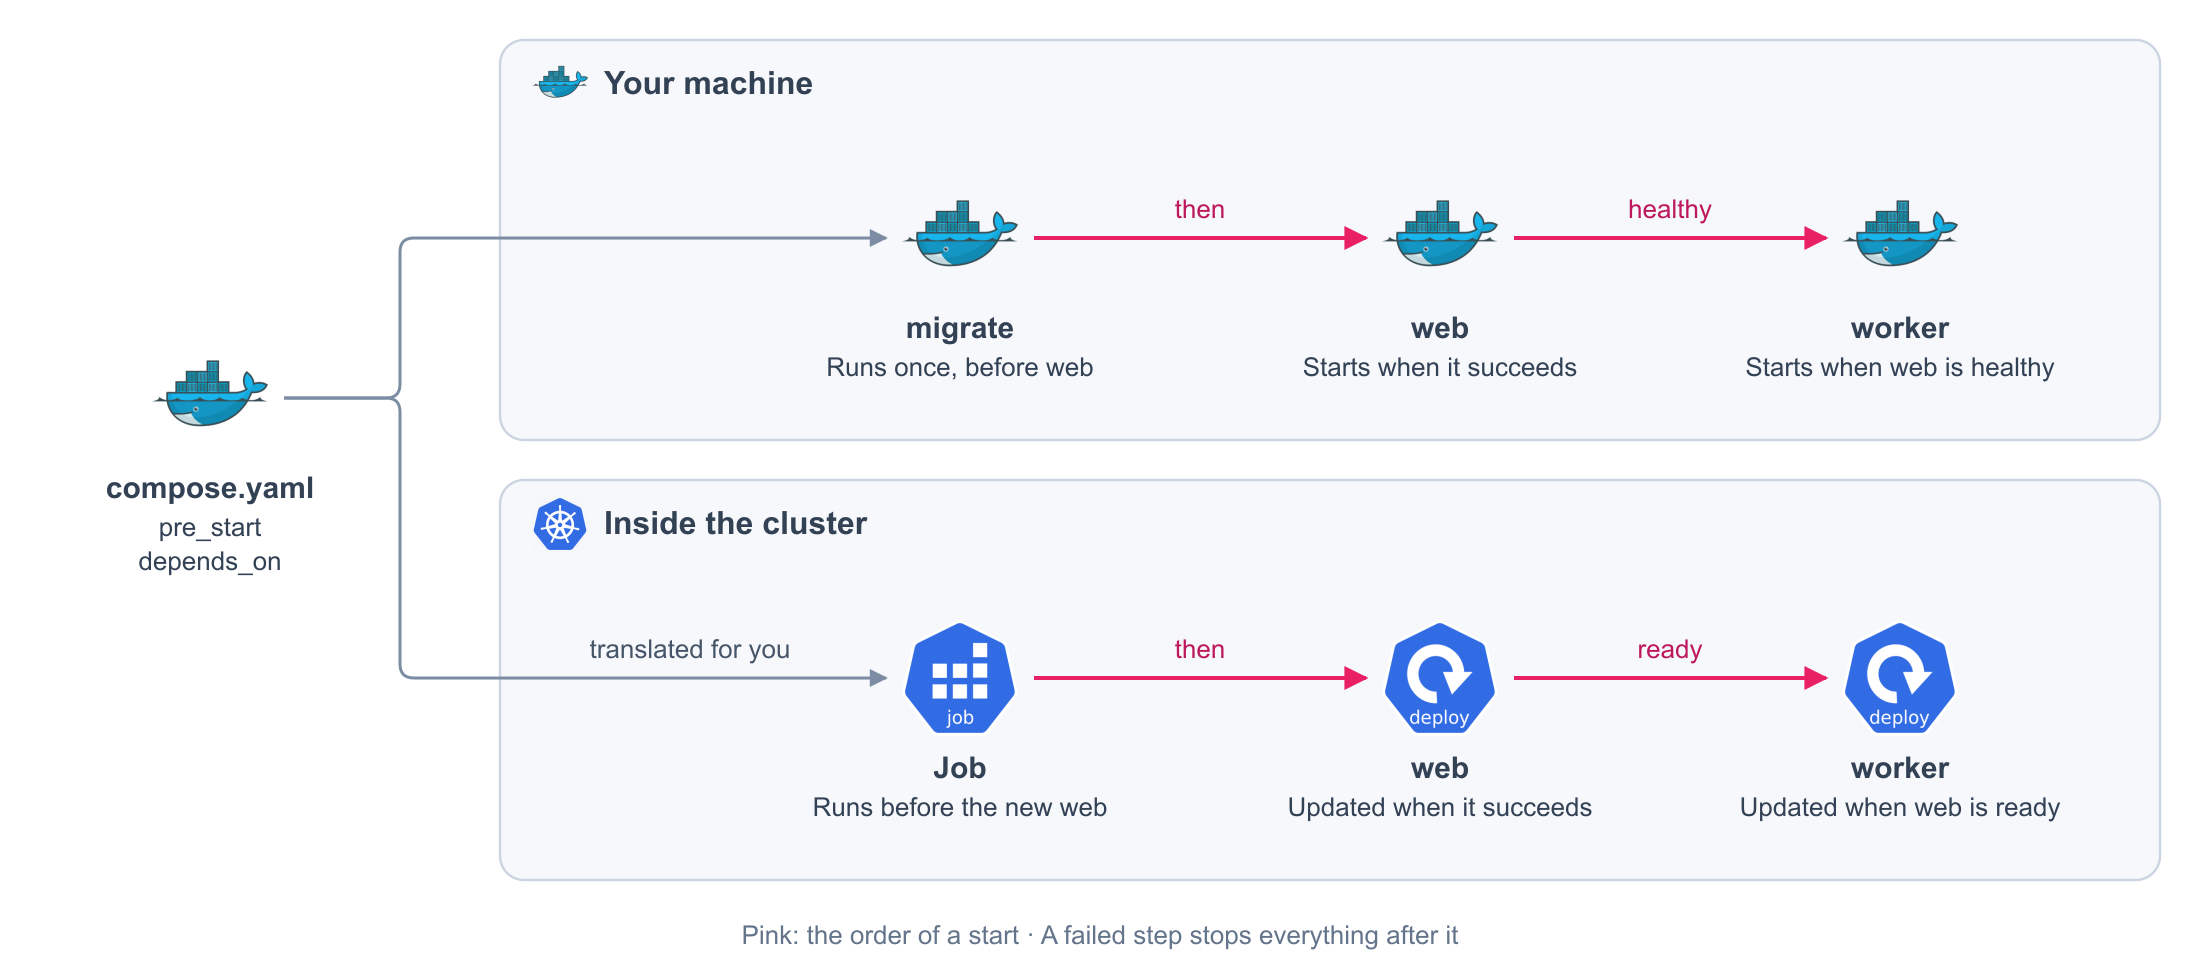
Run a migration, or any other task, before your service starts. The service starts only when the task succeeds.
compose.staging.yaml
services:
  web:
    image: my-app:local
    command: [python, manage.py, runserver, "0.0.0.0:8000"]
    secrets:
      - DB_PASSWORD # (1)!
    healthcheck:
      test: [CMD, curl, --fail, http://localhost:8000/healthz]
      interval: 10s
    pre_start:
      - command: [python, manage.py, migrate, --noinput] # (2)!
        environment:
          DB_PASSWORD: ${DB_PASSWORD:?Missing DB_PASSWORD} # (3)!
  worker:
    image: my-app:local
    command: [python, worker.py]
    depends_on:
      web:
        condition: service_healthy # (4)!

secrets:
  DB_PASSWORD: # (5)!
    file: secrets/staging/web/DB_PASSWORD.txt
- The service reads the secret as a file, as in Secrets.
- A command that ends. It runs with the image and the settings of the service.
- The task receives the same secret as a variable. The variable is named like the secret.
- The worker waits for the health check of
webto pass. - A secret named like the variable that the task reads.
Generated on every release. You never write these files or see them.
The task runs first, as a Job, with the secret from the cluster.
apiVersion: batch/v1
kind: Job
metadata:
  annotations:
    argocd.argoproj.io/hook: Sync # (1)!
    argocd.argoproj.io/hook-delete-policy: BeforeHookCreation # (2)!
    argocd.argoproj.io/sync-wave: '0' # (3)!
  labels:
    com.docker.compose.project: my-app
    com.docker.compose.service: web
  name: web-init-1
  namespace: my-app
spec:
  backoffLimit: 0 # (4)!
  template:
    metadata:
      labels:
        com.docker.compose.project: my-app
        com.docker.compose.service: web
        compose.blackstorm.dev/role: pre-start # (5)!
        com.docker.compose.network.default: 'true'
    spec:
      containers:
      - args:
        - python
        - manage.py
        - migrate
        - --noinput
        env:
        - name: DB_PASSWORD
          valueFrom:
            secretKeyRef: # (6)!
              key: value
              name: db-password
        image: my-app:local
        imagePullPolicy: IfNotPresent
        name: web
      restartPolicy: Never # (7)!
- Part of every release: the task runs each time a release is deployed.
- The run of the previous release is removed when a new one starts.
- The order. Lower numbers go first: the task at
0, thenwebat1, thenworkerat2. - No retries. If the task fails, the release stops here.
- Marks the containers of the task. The address of
webnever sends them traffic. - The value comes from the Secret of the cluster, never from a file in the release.
- When the command ends, the container is not started again.
Then web, and then worker. The numbers give the order.
apiVersion: apps/v1
kind: Deployment
metadata:
  annotations:
    argocd.argoproj.io/sync-wave: '1' # (1)!
  labels:
    com.docker.compose.project: my-app
    com.docker.compose.service: web
  name: web
  namespace: my-app
- After the task succeeded.
apiVersion: apps/v1
kind: Deployment
metadata:
  annotations:
    argocd.argoproj.io/sync-wave: '2' # (1)!
  labels:
    com.docker.compose.project: my-app
    com.docker.compose.service: worker
  name: worker
  namespace: my-app
- After
webis ready, which is whatdepends_onasked for.
With two copies, it still runs once
A task runs once for the service, not once for each copy. With deploy.replicas: 2, the
migration runs one time, and then the two copies start.
Fields
| Field | Required | Default | Values |
|---|---|---|---|
pre_start[].command |
Yes | A command that ends, as a list | |
pre_start[].environment |
No | Variables for the task. ${NAME:?message} takes the value of the secret NAME |
|
pre_start[].image |
No | The image of the service | Another image for the task |
pre_start[].working_dir |
No | The one of the service | Where the command starts |
depends_on.<service>.condition |
No | service_healthy waits for the health check of that service. service_started waits the same |
What you get
On your machine
| Behavior | Detail |
|---|---|
| Before the service | Each task runs in its own container, in order, before the service starts |
| Once per service | Not once per copy. Starting or scaling the service again does not repeat a task that succeeded |
| A failure stops the start | The service does not start, and neither do the services that wait for it |
| The secret as a variable | The task reads DB_PASSWORD from its environment. The service keeps reading its file |
On the cluster
| Behavior | Detail |
|---|---|
| Before the new version | Each task runs as a Job before the service is updated |
| A failure keeps the old version | The new version is not applied. The copies that were running keep running |
| It can run again | A later release runs the tasks again. Write them so that running twice is harmless |
| No traffic | The containers of a task never receive requests |
| Order | A service starts after the tasks and services it depends on |
Rules
| Rule | Detail |
|---|---|
| The variable is named like the secret | ${DB_PASSWORD} takes the value of the secret declared as DB_PASSWORD |
| A secret is the whole value | ${DB_PASSWORD} cannot be part of a longer value, such as a connection URL |
| Only permanent services | A scheduled job cannot declare pre_start |
| Once per service | per_replica: true is rejected |
| No other user | user and privileged in a task are rejected |
| A dependency has a health check | service_healthy needs a healthcheck on the service you wait for |
| No waiting for a task | service_completed_successfully is rejected. Use pre_start on the service that needs the task |
| No cycles | Two services cannot wait for each other |